In this challenge we were provided with a netcat session, which would respond with one of 20 random dynamically generated shellcodes encoded as hex.
The session would then prompt for an answer, which would satisfy the shellcodes input check.
The goal of the challenge was to find a way to dynamically solve all 20 binaries, which would then give the flag. Since the binaries would have a different solution every time, it was not possible to just reverse them one by one and some kind of dynamic solve script was required.
It’s important to note that each binary differed in how it accepted user input, which could either be via. path, a file, a socket etc.. This was randomized each run, and therefore using a tool like angr, seemed to bring way too much overhead into the equation, as we would not even have to make the binary run. We would also have to make angr solve it afterwards.
We therefore decided to write our own solve scripts to solve these binaries dynamically
The binaries
We quickly realized that all the binaries sent, although they would have different answers each time, relied on 5 different ways of checking the user input.The way used to check the user input was determined by the number of the binary (1-20) mod 5.
The binary check mechanisms were as follows:
Checks whether the user input is equal to a string found in the binary (we called it base64 since it looks like base64)
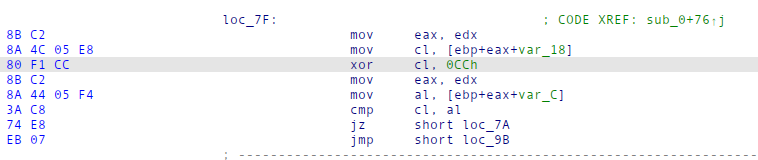
Checks whether the user input is equal to an array of 10 chars xored with a static value
Checks whether the user input satisfies a CRC32 check of a specified length, ASCII only
Generates a table from a string and transforms the userinput, then checks the user input against the table and xors it with a hardcoded value
Checks whether the user input is equal to two arrays of variable length added together.
Knowing this, we could start working on dynamically extracting the information we needed from the binaries and creating algorithms to solve them dynamically.
We opted to find unique byte sequences each type of binary shared, then indexing into the binary to extract the information we needed
Binary 0
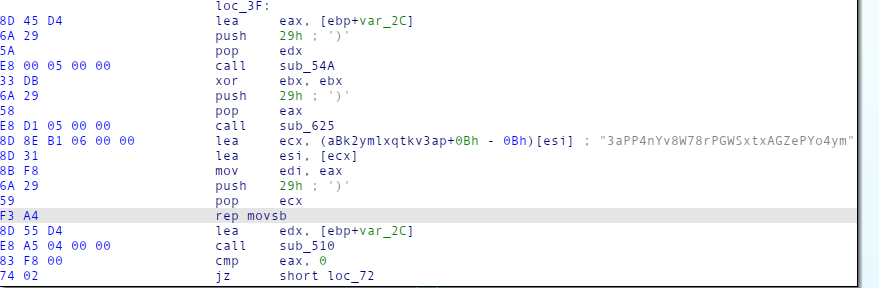
For this we just needed to extract the string within the binary. We noticed that all binaries of this trype, no matter the iteration, had a “rep movsb” instruction right after loading the offset of the string:
This meant we could just find the occurence of this instruction, then index backwards inside the binary to find the offset of the string and extract it:
Implementation:
1
2
3
4
5
6
defsolve_base64(data):idx=data.find(b'\xF3\xA4')#Grab rep movsbinstrs=data[idx-0xd:][:0x20]#Find lea instruction, loading stringoff=u16(instrs[2:2+2])#Get the string offsetb64_data=data[off:].split(b"\x00")[0]#Get the extract the string, we know it ends at a null bytereturnb64_data
Binary 1
For this we need to extract 2 things. We need to extract the character array it checks our input against along with the xor value.
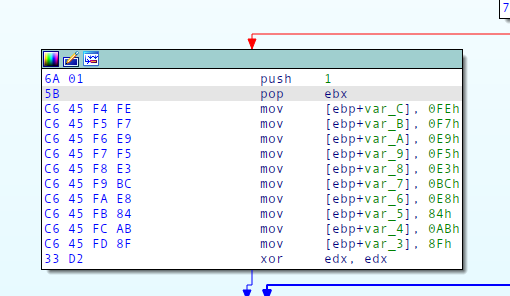
Every binary contains a pop ebx, before the array is allocated, following by the mov instructions:
This allows us to searc for the bytes of pop ebx and the first bytes of the mov instruction to find the beginning of the allocation of the array.
Since each mov instruction is exactly 4 bytes long, we can then extract 40 bytes forward and grab the last 2 bytes of each using string manipulation.
This one is a bit more complicated as it requires us to extract the CRC32 target value along with the desired length of the input.
We then need to find an input string consisting of only ASCII characters, which satisfies these constraints.
After talking it over we agreed on solving this using z3, but as none of us solving this challenge had any idea of how to actually solve stuff using z3, we opted to find existing implementations.
Unfortunately we could not find an implementation where we could supply a length and stay within the constraints of ascii, so we decided to instead glue 2 different scripts together and call it a day.
The scripts were:
https://gist.github.com/percontation/11310679 which constrains the search space to only ascii but can only solve if the length is a multiple of 4 (as it deals only with 32 bit blocks)
We then found our best superglue and duct tape and did some arts and crafts to create a z3 solver which fit our constraints.
Extracting the goal CRC and length from these binaries wasn’t a one fit all solution, we had to write 3 different functions to extract these values:
solve_two which solves binary 2
solve_seven which solves binary 7 and 17
solve_twelve which solves binary 12.
Extraction of these values worked about the same way as in earlier examples. Once we had the values we ran it through our super duper best written z3 solver ever created (which definetely wasn’t hacked together hapharzardly).
The implementation of the aforementionened solvers can be seen here:
polynomial=0xEDB88320deff_crc32(data,size,prev=0):crc=prev^0xFFFFFFFFforiinrange(0,size,8):crc=crc^(z3.LShR(data,i)&0xFF)for_inrange(8):crc=If(crc&1==BitVecVal(1,size),z3.LShR(crc,1)^polynomial,z3.LShR(crc,1))returncrc^0xFFFFFFFFdefisAscii(bv,shamt):# Note the use of z3.And here. Using python's `and` would be incorrect!returnAnd(32<=(LShR(bv,shamt)&0xff),(LShR(bv,shamt)&0xff)<127)defsolve_seven(data):off=data.find(b"\x3B\xC6\x74\x02")input_len_off=off-7input_len=data[input_len_off]print("input length",hex(input_len))crc_val_off=off-0xfcrc_val=u32(data[crc_val_off:crc_val_off+4])print(f"crc: {crc_val:#x}")size=input_len*8target=crc_vals=z3.Solver()data=z3.BitVec('data',size)s.add(f_crc32(data,size)==target)foriinrange(input_len):s.add(isAscii(data,i*8))ifs.check()==z3.sat:result=long_to_bytes(int(str(s.model()[data])))else:print("unsat :(")exit(0)returnresult[::-1]defsolve_twelve(data):off=data.find(bytes.fromhex("59 F3 A4 33 DB"))input_len_off=off-1input_len=data[input_len_off]print("input length",hex(input_len))crc_val_off=off+6crc_val=u32(data[crc_val_off:crc_val_off+4])print(f"crc: {crc_val:#x}")size=input_len*8target=crc_vals=z3.Solver()data=z3.BitVec('data',size)s.add(f_crc32(data,size)==target)foriinrange(input_len):s.add(isAscii(data,i*8))ifs.check()==z3.sat:result=long_to_bytes(int(str(s.model()[data])))else:print("unsat :(")exit(0)returnresult[::-1]defsolve_two(data):off=data.find(b"\x8D\x45\x98")input_len_off=off+20input_len=data[input_len_off]print("input length",hex(input_len))crc_val_off=input_len_off+12print(hex(crc_val_off))crc_val=u32(data[crc_val_off:crc_val_off+4])print(f"crc: {crc_val:#x}")size=input_len*8target=crc_vals=z3.Solver()data=z3.BitVec('data',size)s.add(f_crc32(data,size)==target)foriinrange(input_len):s.add(isAscii(data,i*8))ifs.check()==z3.sat:result=long_to_bytes(int(str(s.model()[data])))print(hex(zlib.crc32(result[::-1])))else:print("unsat :(")exit(0)returnresult[::-1]
Binary 3
Binary 3 again required us to write 3 solve functions as we had no consistent way of extracting the data we needed consistently.
We needed to extract:
The answer xor values for after transforms
The input for the table creation (a string located in the binary)
The input length
For solving this one we created a function to emulate the creation of the table:
The 2 other functions look the same, but just extracts different offsets in the binary.
In the end we created 3 functions with the following functionality:
solve_three, solves binary 3
solve_eight, solves binary 8 and 13
solve_eigtheen, solves binary 18
Binary 4
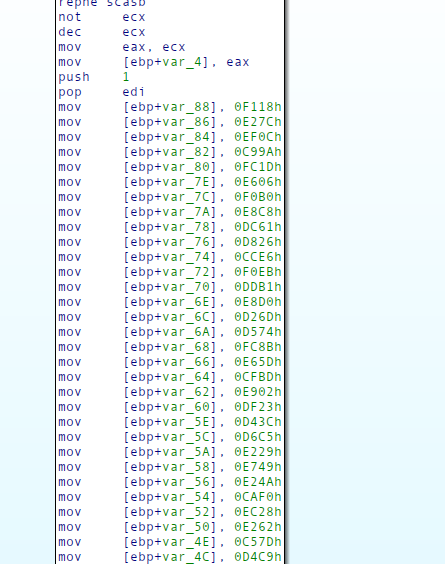
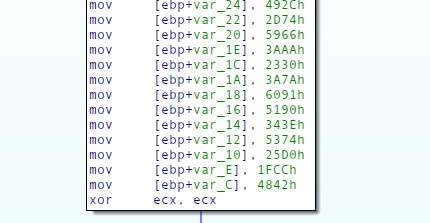
For binary 4 we needed to extract the 2 different arrays created, which came right after each other.
Luckily binary 4 and it’s counterparts had almost the same instructions right before allocating the string on the stack. They either had:
1
2
push1;popedi;
or
1
2
push1;popesi;
We realized that if we search for push 1; pop edi but it ends up not using that sequence, when allocating the string, the index returned will be below 100. We can therefore first search for that sequence, check whether or not the index we find, is above or below 100 and if it is, we just search for the other sequence.
Since the arrays are a variable length, we also needed to figure out how big they were. Luckily they all end with the same instruction after allocating all the variables on the stack:
We can therefore just look from the start offset untill we hit the xor ecx, ecx instruction.
Since both arrays get allocated in one big mess, we don’t have an exact value we can find for how big they are. But since they are both the same length, we can just extract the full thing and then split the array in half to get two seperate ones.
Then all we need to do is subtract one from the other, then and the result with 0xffff to emulate underflows.